Introduction
DevOps for startups isn't about copying what Netflix or Google do. It's about a small team shipping often without breaking things, and without one engineer becoming the only person who knows how production works.
Most startups don't fail because their infrastructure was wrong. But many lose months to slow, fragile releases, surprise cloud bills, a security questionnaire they can't answer, or a key engineer leaving with all the deployment knowledge in their head. DevOps practices prevent each of those, and they're far cheaper to adopt at five engineers than at fifty.
This guide covers why DevOps matters more for startups than for large companies, the minimum to set up first, what to add at each funding stage, when Kubernetes is (and isn't) worth it, how to keep cloud costs and compliance under control, and when to hire versus outsource.
Why DevOps matters more for startups than for big companies
A large company can absorb a bad release, a week of downtime or an overpriced cloud bill. A startup often can't. Four things make DevOps disproportionately valuable early:
- Speed is the main advantage you have. Shipping small changes daily lets you learn from customers faster than larger competitors.
- Every engineer is expensive. Automation stops your best developers from spending Friday afternoons on manual deployments.
- Runway is finite. In usage-priced clouds, a forgotten test cluster or an oversized database can quietly cost weeks of runway.
- Habits set early are hard to change. Infrastructure clicked together in the console becomes a liability when you need to scale, pass an audit or onboard new hires.
The problems DevOps solves for a startup
The original post named four problems, and they still apply: infrequent deployments, crashes at release time, no automated testing and slow bug fixes. In 2026 terms, here's what causes each and how DevOps fixes it.
| Problem | Typical cause | DevOps fix |
|---|---|---|
| Releases are rare and scary | Big batches of changes, manual steps | Small pull requests, CI/CD on every merge |
| Code passes staging, fails in production | Environments that differ; config set by hand | Infrastructure as code; identical environments |
| Bugs found by customers | No automated tests in the pipeline | Tests run on every change; preview environments |
| Slow to diagnose incidents | Logs scattered, no alerts | Centralized logging, metrics and alerts from day one |
| [NEW] One person knows how prod works | Tribal knowledge, no documentation | Everything in Git; runbooks; shared on-call |
The original described a split where the operations team containerizes and deploys what developers hand over. That handoff is exactly what DevOps removes: the team that builds a service also packages, ships and watches it, with automation doing the repetitive parts.
Minimum viable DevOps: what to set up first
You don't need a platform team or a service mesh in your first year. You need five things, and most can be set up in a week:
- Git for everything, including infrastructure and configuration, with pull requests and code review.
- CI/CD with GitHub Actions or GitLab CI: run tests on every pull request and deploy automatically from the main branch.
- Infrastructure as code with Terraform or OpenTofu, so environments can be recreated in minutes, not rebuilt from memory.
- Basic observability: centralized logs, a few dashboards, and alerts on errors and latency that reach a phone.
- Guardrails: a billing budget alert, multi-factor authentication on every account, and no shared root credentials.
DevOps by startup stage
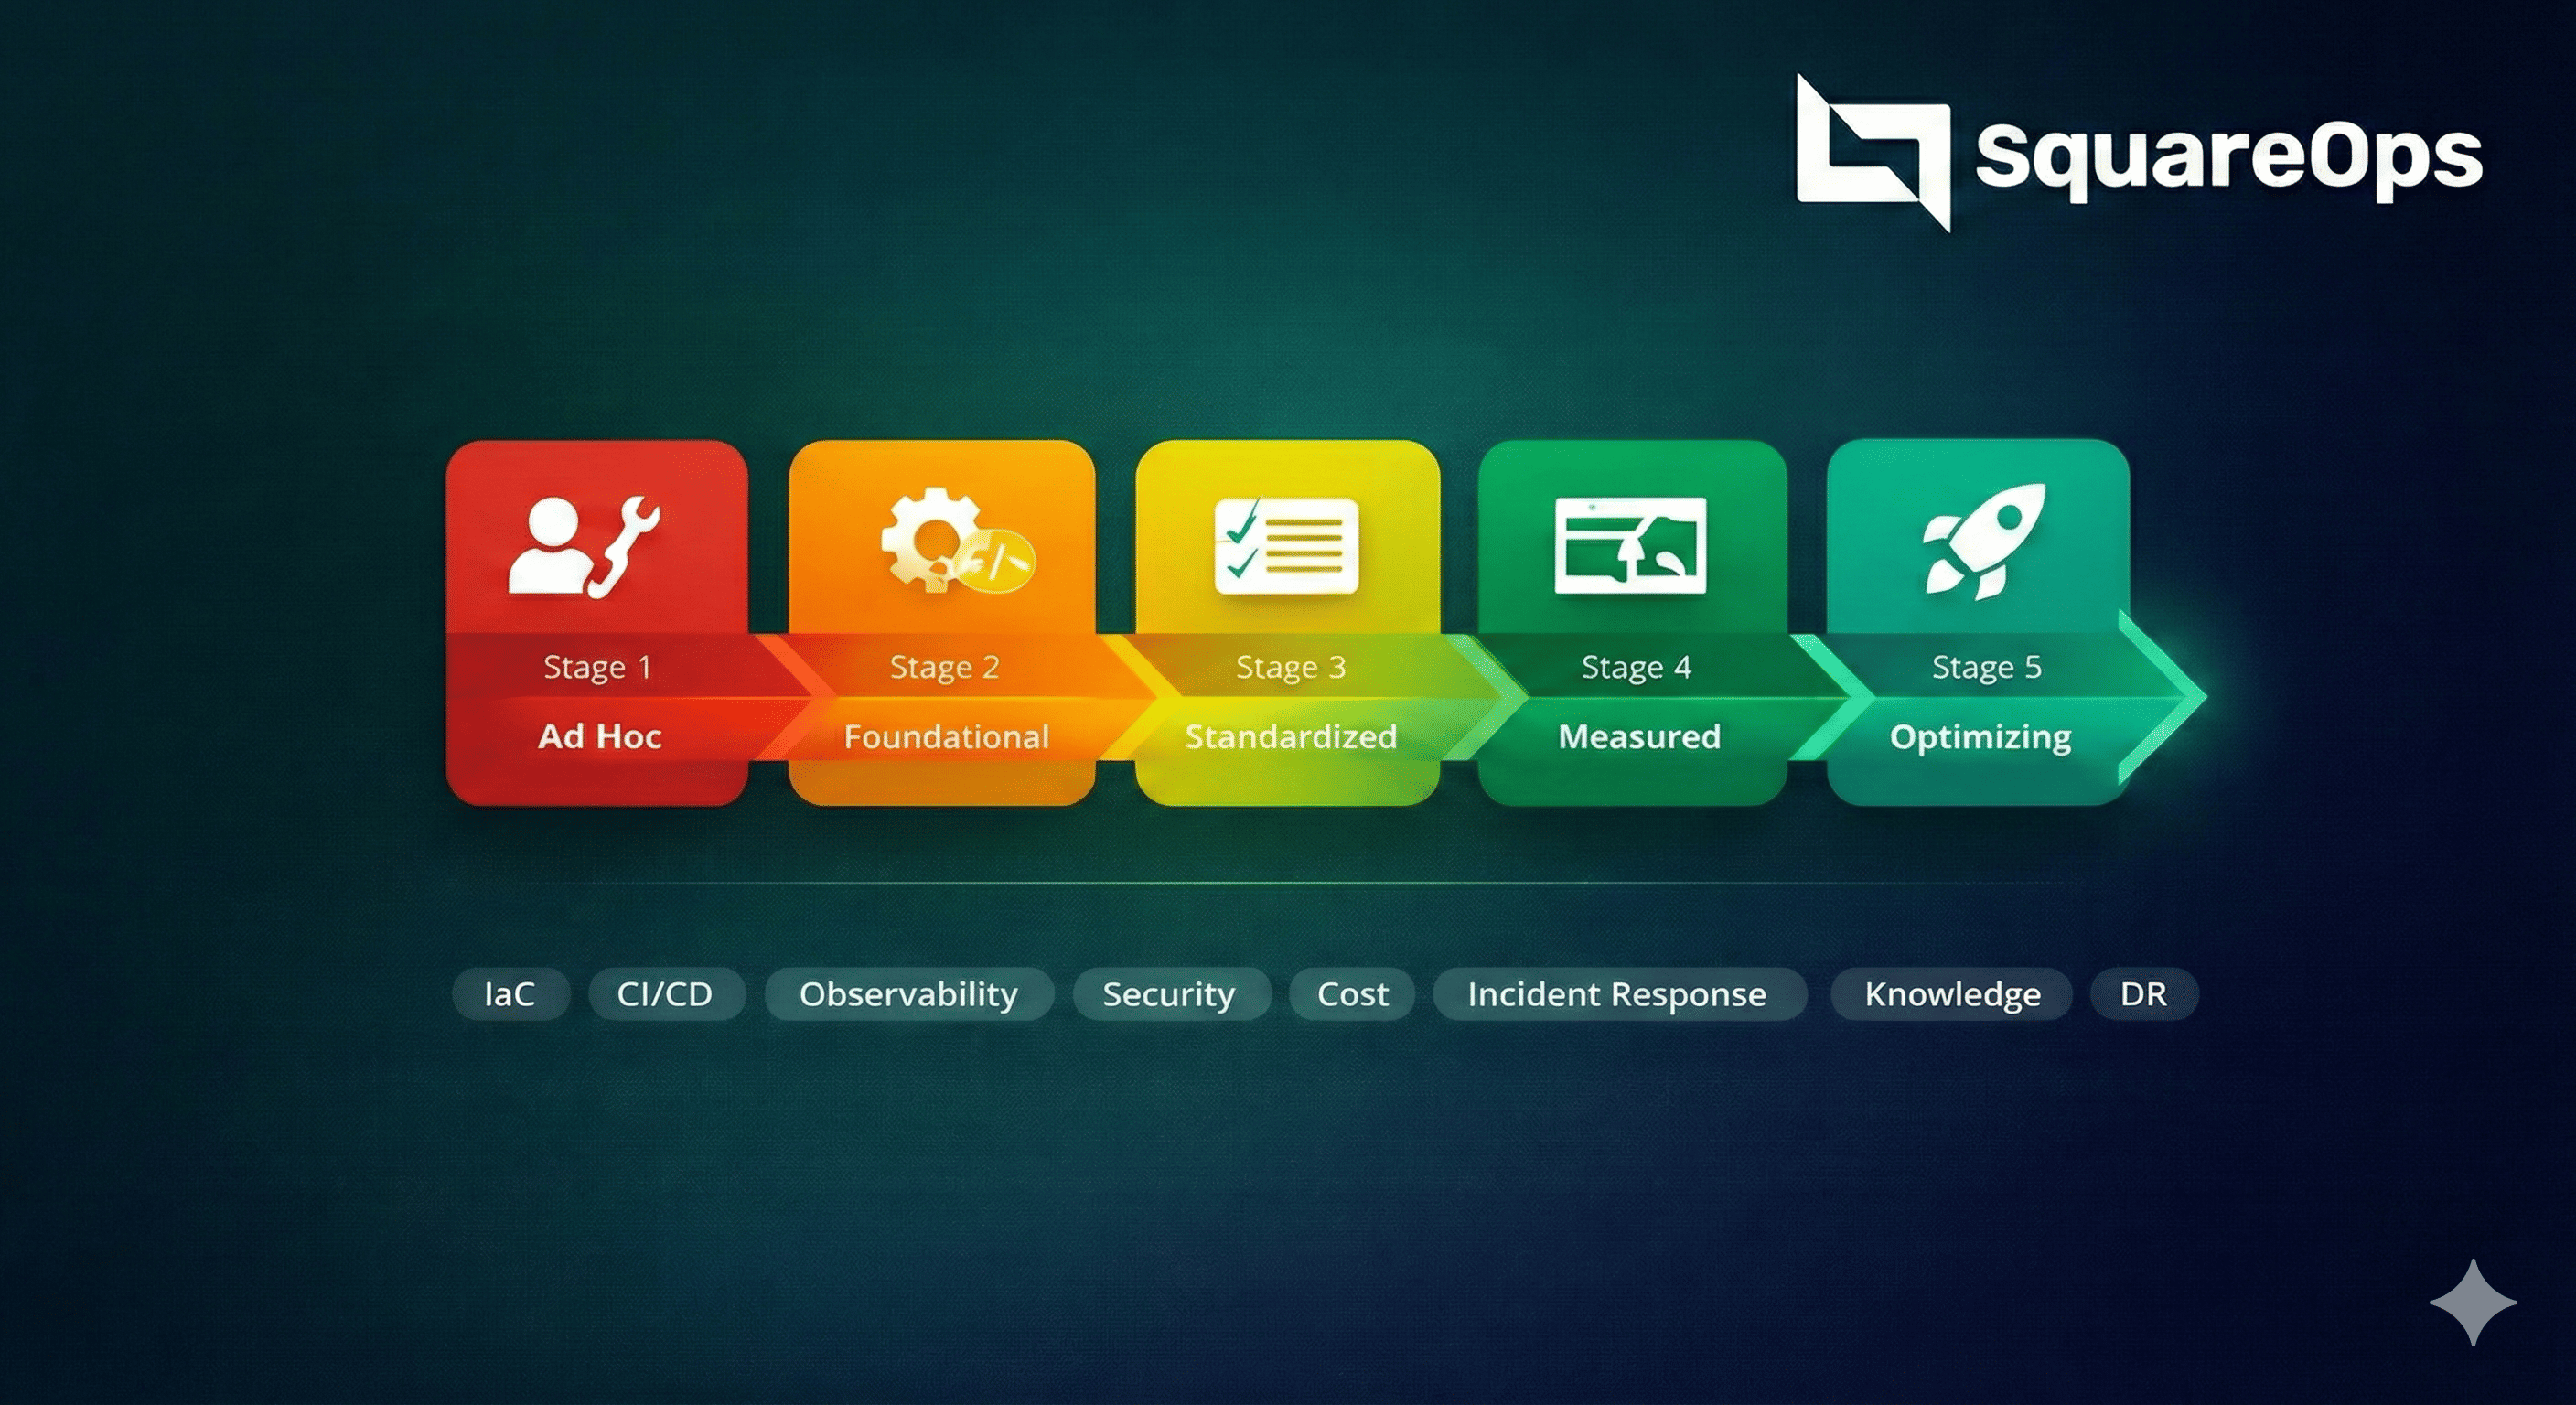
What "good DevOps" means changes as you grow. Add practices when the pain they solve appears, not before.

Pre-seed and MVP (1–5 engineers)
Goal: ship and learn. Use the minimum viable DevOps above, a single cloud account (or a production and a development account), and managed services wherever possible. Deploy straight from the main branch. Apply for cloud credits: AWS Activate offers $1,000 to self-funded startups (up to $5,000 for some) and up to $200,000 to startups backed by an Activate Provider such as a VC or accelerator.
Seed: first paying customers (5–15 engineers)
Goal: don't lose customers to outages. Add a staging environment that matches production, automated database backups you've actually restored, uptime monitoring and a simple on-call rota. Separate production and development into different cloud accounts. Start tagging resources so you can see what each environment costs.
Series A: scaling the team (15–50 engineers)
Goal: keep shipping fast as headcount grows. Standardize pipelines and service templates so new engineers deploy on day one. Introduce preview environments, feature flags and progressive delivery (canary or blue-green). Enterprise customers will start sending security questionnaires, so this is usually when SOC 2 work begins. If you're running many services, this is also the earliest point where Kubernetes may pay off.
Series B and beyond: platform and compliance (50+ engineers)
Goal: scale without chaos. A small platform team builds self-service "golden paths" so product teams don't each reinvent infrastructure. Add a multi-account landing zone, formal incident management with service level objectives, and a FinOps review each month. See our guide to golden paths in platform engineering.
Do you need Kubernetes yet?
The original post told the story of moving from microservices to Docker to Kubernetes as if each step were inevitable. For most startups, Kubernetes is the wrong first step. It adds real operational work: upgrades, networking, autoscaling and security, plus a control-plane fee on Amazon EKS of $0.10 per cluster-hour (about $73 a month) that rises to $0.60 if you fall behind on Kubernetes versions.
Kubernetes starts to make sense when several of these are true:
- You run more than a handful of services with different scaling needs
- You need portability across clouds or on-premises
- You have, or can rent, people who know how to operate it
- Managed container services such as Amazon ECS on Fargate are holding you back
If you do adopt it, use a managed service, autoscale nodes with Karpenter, and deploy with GitOps. Our managed Kubernetes team runs EKS for startups that want the benefits without the on-call load.
Keeping cloud costs under control
Cloud cost is a DevOps concern because the people who deploy infrastructure are the ones who create the bill. Five habits protect your runway:
- Set an AWS Budgets alert on day one, and Cost Anomaly Detection soon after.
- Tag every resource with an owner and environment.
- Shut down non-production environments at night and on weekends.
- Prefer serverless and managed services that scale to zero for spiky workloads.
- Buy Savings Plans only once usage is steady, and only for the baseline.
Credits are a bridge, not a strategy: plan for the month they run out. Our AWS cost optimization guide covers the detail.
Security and compliance from day one
The first large customer will usually ask for a security questionnaire, and often for a SOC 2 report. Startups that built DevOps habits early find this far easier because the evidence already exists: every change reviewed in Git, every deployment logged, access controlled through single sign-on.
Start with the basics: multi-factor authentication everywhere, no long-lived access keys, secrets in a secrets manager, dependency and container scanning in CI, encrypted databases and tested backups. If you sell into India, plan for the DPDP Rules, which add security and breach-reporting obligations from May 2027. See our DevSecOps service and our guide to SOC 2 audits.
Using AI without breaking production
AI coding assistants can make a small team feel much larger. Google Cloud's 2025 DORA report found 90% of technology professionals now use AI at work, but also that AI adoption is associated with less stable software delivery when the basics are weak (Google Cloud). For a startup, that means three rules: require tests and review for AI-written code, keep a human approving production changes, and never paste secrets or customer data into tools you haven't vetted.
How to measure progress
The original quoted 2019 figures comparing "elite" and "low" performers. A more useful habit is to track your own numbers with DORA's four metrics:
| Metric | What it tells you | A healthy early-stage target |
|---|---|---|
| Deployment frequency | How often you ship | Daily or more |
| Change lead time | Commit to production | Under a day |
| Change failure rate | Share of releases causing problems | Low and falling |
| Failed deployment recovery time | How fast you recover | Under an hour |
Targets are SquareOps' guidance for small teams, not DORA benchmarks. Measure monthly; the trend matters more than the number.
Hire, outsource or both?
The original recommended outsourcing for startups "too young to afford an in-house DevOps unit." That's often right, but not always. Here's how to decide:
| Option | Best when | Watch out for |
|---|---|---|
| Developers own it | Pre-seed, simple stack on managed services | Ops work slowly crowds out product work |
| Outsource to a DevOps partner | Seed to Series A; need production-grade setup fast; no ops hire yet | Make sure you own every repo and can take it back |
| First in-house hire | Infrastructure is core to the product, or you're past ~20 engineers | One person becomes a single point of failure |
| Hybrid | Series A onward: in-house lead plus partner for 24x7 and specialist work | Clear split of responsibilities |
Whichever you choose, insist that everything lives in code in your repositories, so knowledge stays with the company.
How SquareOps helps startups
SquareOps is a cloud-native DevOps and managed services company based in Gurugram, working with startups across India, the US, the UK, Europe and the Middle East. We typically help in three ways:
- Foundations: CI/CD, Terraform and a secure AWS setup, built in code you own, using our open-source Terraform modules for Amazon EKS where they fit
- Ongoing operations: 24x7 SRE and managed Kubernetes so founders aren't carrying the pager
- Self-service: our Atmosly platform for teams that want developers to spin up environments themselves
[NEW] Startup example: [ADD a real, named startup client with approval. Strong candidates from the case studies page include DexKor ("zero infrastructure to production on AWS EKS in one week") and Nimbbl (40 engineers self-managing Kubernetes environments). Add two measured outcomes, such as deployment frequency or time to onboard a new engineer.]
Conclusion
The original's advice still stands: adopt DevOps practices from day one. What's changed is how much easier and cheaper that has become. A small team can have CI/CD, infrastructure as code and good monitoring running in a week, and add the rest stage by stage as the business grows.
If you'd like a production-ready foundation without hiring a DevOps team yet, talk to SquareOps.